Deal of The Day! Hurry Up, Grab the Special Discount - Save 25% - Ends In 00:00:00 Coupon code: SAVE25

Welcome to Pass4Success

- Free Preparation Discussions

Google Professional Machine Learning Engineer Exam - Topic 3 Question 114 Discussion

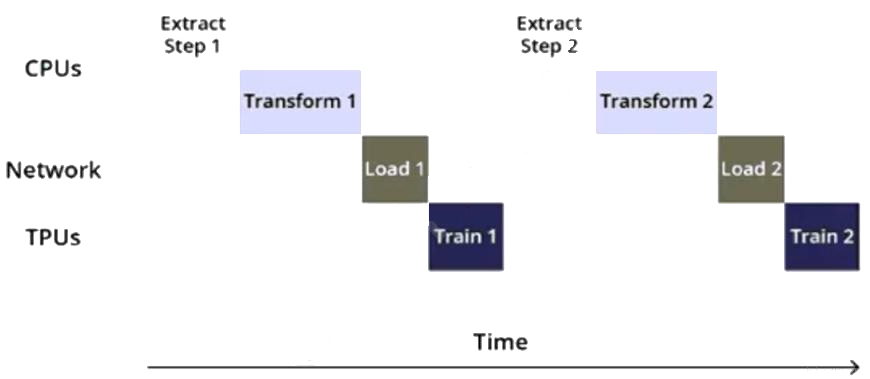
You are training an object detection model using a Cloud TPU v2. Training time is taking longer than expected. Based on this simplified trace obtained with a Cloud TPU profile, what action should you take to decrease training time in a cost-efficient way?
D) Rewrite your input function using parallel reads, parallel processing, and prefetch.
A) Move from Cloud TPU v2 to Cloud TPU v3 and increase batch size.
B) Move from Cloud TPU v2 to 8 NVIDIA V100 GPUs and increase batch size.
C) Rewrite your input function to resize and reshape the input images.

Google Professional Machine Learning Engineer Exam - Topic 3 Question 114 Discussion

Actual exam question for Google's Professional Machine Learning Engineer exam
Question #: 114
Topic #: 3
[All Professional Machine Learning Engineer Questions]

You are training an object detection model using a Cloud TPU v2. Training time is taking longer than expected. Based on this simplified trace obtained with a Cloud TPU profile, what action should you take to decrease training time in a cost-efficient way?

Show Suggested Answer Hide Answer
Suggested Answer: D

The trace in the question shows that the training time is taking longer than expected. This is likely due to the input function not being optimized. To decrease training time in a cost-efficient way, the best option is to rewrite the input function using parallel reads, parallel processing, and prefetch. This will allow the model to process the data more efficiently and decrease training time.Reference:

[Cloud TPU Performance Guide]

[Data input pipeline performance guide]


Contribute your Thoughts:

0/2000 characters
Mabelle
4 days ago
Definitely! D covers multiple improvements at once.
upvoted 0 times
...
Felicidad
9 days ago
I feel like option C could help too, but D seems more comprehensive.
upvoted 0 times
...
Quentin
14 days ago
True, but it might not be as cost-effective as optimizing the input function.
upvoted 0 times
...
Domonique
19 days ago
But what about option A? Upgrading to TPU v3 could help.
upvoted 0 times
...
Ivette
24 days ago
I agree! It’s cost-efficient too. No need for expensive hardware.
upvoted 0 times
...
Mayra
30 days ago
I think option D is the best. Parallel processing can really speed things up.
upvoted 0 times
...
Dona
1 month ago
C is a good start, but I’d go with D for maximum efficiency.
upvoted 0 times
...
Louvenia
1 month ago
I disagree, B seems too costly for just a speed boost.
upvoted 0 times
...
Sharan
2 months ago
Wait, can just rewriting the input function really make that much difference?
upvoted 0 times
...
Ciara
2 months ago
I think A is better. TPU v3 is a big upgrade!
upvoted 0 times
...
Arlie
2 months ago
Option D sounds like a solid choice for speeding things up!
upvoted 0 times
...
Dorcas
2 months ago
Wait, can you really save costs by switching to GPUs? Sounds odd!
upvoted 0 times
...
Gearldine
2 months ago
Increasing batch size could lead to better utilization too.
upvoted 0 times
...
Marshall
2 months ago
Not sure about that, resizing images might not help much.
upvoted 0 times
...
Adela
4 months ago
Definitely go with option D, parallel processing is key!
upvoted 0 times
...
Maryann
4 months ago
I heard TPU v3 is way faster than v2.
upvoted 0 times
...
Kerrie
5 months ago
I vaguely recall that increasing the batch size can sometimes lead to better utilization of resources, but I’m not confident if that alone would solve the issue.
upvoted 0 times
...
Percy
5 months ago
I feel like we had a practice question about input functions, and rewriting them could help with performance. Option C seems relevant.
upvoted 0 times
...
Fidelia
5 months ago
I'm not entirely sure, but I think moving to a different TPU version might not be the most cost-efficient solution.
upvoted 0 times
...
Barabara
5 months ago
I remember we discussed how optimizing the input pipeline can significantly reduce training time, so option D might be the best choice.
upvoted 0 times
...

Save Cancel