
 MENU

You are analyzing customer purchases in a Fabric notebook by using PySpanc You have the following DataFrames:

You need to join the DataFrames on the customer_id column. The solution must minimize data shuffling. You write the following code.

Which code should you run to populate the results DataFrame?
A)

B)

C)

D)
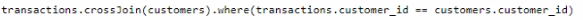
Suggested Answer: A
Get Premium DP-600 Questions
as Interactive Web-Based Practice Test or PDF
Real Exam Format
Detailed Explanations
Instant Access
Get Your Practice Test
32 comments · newest first
DE
Deangelo
11 months ago
I agree, minimizing data shuffling is key for performance!
ER
Erick
11 months ago
Wait, why is data shuffling a concern here?
CA
Carlota
11 months ago
Not sure about that, I feel like Option D might work better.
NO
Norah
12 months ago
I think Option B is the best choice!
KA
Kathrine
12 months ago
Looks like we need to join on customer_id for sure.
CO
Corrie
1 year ago
I keep second-guessing myself on this. I thought option B looked good, but now I'm unsure if it really minimizes shuffling as required.
VI
Vilma
1 year ago
I have a vague recollection of a similar question where we had to consider the order of operations. I hope I remember it correctly for this one.
SA
Santos
1 year ago
I'm not entirely sure, but I feel like option C might be the right choice. It seems to align with what we practiced about DataFrame joins.
LA
Lashawn
1 year ago
I remember we discussed minimizing data shuffling during our practice sessions. I think it might be related to how the join is structured.
CA
Candida
1 year ago
This seems straightforward. Based on the requirement to minimize data shuffling, I think Option B is the way to go. The `merge()` function with the `how='left'` parameter should do the trick.
DO
Dorian
1 year ago
I'm a bit confused by the different join methods presented. I'll need to refresh my understanding of how each one works before deciding which one is the most appropriate for this scenario.
AR
Arlyne
1 year ago
Hmm, this looks like a tricky one. I'll need to carefully review the DataFrames and the code options to determine the best approach that minimizes data shuffling.
EM
Emerson
1 year ago
Okay, let me think this through step-by-step. The key is to find the join method that will work efficiently with the given DataFrames. I'll need to consider the performance implications of each option.
ED
Edmond
1 year ago
This looks pretty straightforward. I'm pretty confident I can identify the 3 main considerations they're looking for here based on the information provided.
CE
Ceola
1 year ago
I think the best approach is to start with the technology architecture to understand the current infrastructure capabilities. That will help us sequence the projects in the most optimal way to realize the CEO's vision.
LO
Loren
1 year ago
Okay, I've got this. The key is to calculate the tenure in weeks using the difference between SYSDATE and the hire_date, and then either TRUNC or ROUND that value to get the number of complete weeks. Option A looks good to me.
BE
Beatriz
2 years ago
Interesting, why do you think code C could be a good choice?
SH
Shasta
2 years ago
I think code C may also be a good option to consider.
SH
Sharita
2 years ago
Code A minimizes data shuffling more effectively than code B.
BE
Beatriz
2 years ago
Why do you think code A is better?
SH
Sharita
2 years ago
I disagree, I believe code A is the better choice.
BE
Beatriz
3 years ago
I think the best option is to run code B.
LO
Louann
3 years ago
Haha, good one! I'll make sure to keep my notes in a Fabric notebook, just like the one in the question. Definitely the most efficient way to study for this exam.
JE
Jean
3 years ago
Exactly! I'm going with option C. It just makes the most sense for this scenario. Now, if only the exam had a question about the best way to store my exam notes... *wink wink*
PE
Peter
3 years ago
Going with option C, thanks for the input.
RO
Rodolfo
3 years ago
Option C it is, no need to overthink it.
CO
Corinne
3 years ago
Agreed, option C it is.
XU
Xuan
3 years ago
Let's all choose option C then.
SO
Son
3 years ago
Yeah, option C minimizes data shuffling.
LE
Lettie
3 years ago
Option C seems to be the best choice here.
AL
Alise
3 years ago
I think I will go with option C as well.
PE
Peter
3 years ago
Ooh, good catch! Option C does seem like the winner here. Broadcast joins are great for minimizing data movement, especially when one of the DataFrames is small enough to fit in memory on each partition.