
Free Preparation Discussions
 MENU

Workday-Pro-Integrations Exam Questions
- Topic 1: Calculated Fields: This section of the exam measures the skills of Workday Integration Analysts and covers the creation, configuration, and management of calculated fields used to transform, manipulate, and format data in Workday integrations. It evaluates understanding of field types, dependencies, and logical operations that enable dynamic data customization within integration workflows.
- Topic 2: Cloud Connect: This section of the exam measures the skills of Workday Implementation Consultants and focuses on using Workday Cloud Connect solutions for third-party integration. It includes understanding pre-built connectors, configuration settings, and how to manage data flow between Workday and external systems while ensuring security and data integrity.
- Topic 3: Enterprise Interface Builders: This section of the exam measures the skills of Integration Developers and covers the use of Workday’s Enterprise Interface Builder (EIB) to design, deploy, and maintain inbound and outbound integrations. It evaluates the candidate’s ability to create templates, configure transformation rules, schedule integrations, and troubleshoot EIB workflows efficiently.
- Topic 4: Integrations: This section of the exam measures the skills of Integration Specialists and covers the full spectrum of integration techniques in Workday. It includes an understanding of core integration architecture, APIs, Workday Studio, and integration system user setup. The focus is on building scalable, maintainable, and secure integrations that ensure seamless system interoperability.
- Topic 5: Reporting: This section of the exam measures the skills of Reporting Analysts and focuses on building, modifying, and managing Workday reports that support integrations. It includes working with report writer tools, custom report types, calculated fields within reports, and optimizing report performance to support automated data exchange.
- Topic 6: XSLT: This section of the exam measures the skills of Data Integration Developers and covers the use of Extensible Stylesheet Language Transformations (XSLT) in Workday integrations. It focuses on transforming XML data structures, applying conditional logic, and formatting output for various integration use cases such as APIs and external file delivery.
Free Workday Workday-Pro-Integrations Exam Actual Questions
Note: Premium Questions for Workday-Pro-Integrations were last updated On Nov. 05, 2026 (see below)
What is the purpose of a namespace in the context of a stylesheet?
In the context of a stylesheet, particularly within Workday's Document Transformation system where XSLT (Extensible Stylesheet Language Transformations) is commonly used, a namespace serves a critical role in defining the scope and identity of elements and attributes. The correct answer, as aligned with Workday's integration practices and standard XSLT principles, is that a namespace 'provides elements you can use in your code.' Here's a detailed explanation:
Definition and Purpose of a Namespace:
A namespace in an XML-based stylesheet (like XSLT) is a mechanism to avoid naming conflicts by grouping elements and attributes under a unique identifier, typically a URI (Uniform Resource Identifier). This allows different vocabularies or schemas to coexist within the same document or transformation process without ambiguity.
In XSLT, namespaces are declared in the stylesheet using the xmlns attribute (e.g., xmlns:xsl='http://www.w3.org/1999/XSL/Transform' for XSLT itself). These declarations define the set of elements and functions available for use in the stylesheet, such as <xsl:template>, <xsl:value-of>, or <xsl:for-each>.
For example, when transforming Workday data (which uses its own XML schema), a namespace might be defined to reference Workday-specific elements, enabling the stylesheet to correctly identify and manipulate those elements.
Application in Workday Context:
In Workday's Document Transformation integrations, namespaces are essential when processing XML data from Workday (e.g., Core Connector outputs) or external systems. The namespace ensures that the XSLT processor recognizes the correct elements from the source XML and applies the transformation rules appropriately.
Without a namespace, the processor might misinterpret elements with the same name but different meanings (e.g., <name> in one schema vs. another). By providing a namespace, the stylesheet gains access to a specific vocabulary of elements and attributes, enabling precise coding of transformation logic.
Why Other Options Are Incorrect:
B . Indicates the start and end tag names to output: This is incorrect because namespaces do not dictate the structure (start and end tags) of the output. That is determined by the XSLT template rules and output instructions (e.g., <xsl:output> or literal result elements). Namespaces only define the identity of elements, not their placement or formatting in the output.
C . Restricts the data the processor can access: While namespaces help distinguish between different sets of elements, they do not inherently restrict data access. Restrictions are more a function of security settings or XPath expressions within the stylesheet, not the namespace itself.
D . Controls the filename of the transformed result: Namespaces have no bearing on the filename of the output. In Workday, the filename of a transformed result is typically managed by the Integration Attachment Service or delivery settings (e.g., SFTP or email configurations), not the stylesheet's namespace.
Practical Example:
Suppose you're transforming a Workday XML file containing employee data into a custom format. The stylesheet might include:
<xsl:stylesheet version='1.0' xmlns:xsl='http://www.w3.org/1999/XSL/Transform' xmlns:wd='http://www.workday.com/ns'>
<xsl:template match='wd:Employee'>
<EmployeeName><xsl:value-of select='wd:Name'/></EmployeeName>
</xsl:template>
</xsl:stylesheet>
Here, the wd namespace provides access to Workday-specific elements like <wd:Employee> and <wd:Name>, which the XSLT processor can then use to extract and transform data.
Workday Pro Integrations Study Guide Reference:
Workday Integration System Fundamentals: Explains XML and XSLT basics, including the role of namespaces in identifying elements within stylesheets.
Document Transformation Module: Highlights how namespaces are used in XSLT to process Workday XML data, emphasizing their role in providing a vocabulary for transformation logic (e.g., 'Understanding XSLT Namespaces').
Core Connectors and Document Transformation Course Manual: Includes examples of XSLT stylesheets where namespaces are declared to handle Workday-specific schemas, reinforcing that they provide usable elements.
Workday Community Documentation: Notes that namespaces are critical for ensuring compatibility between Workday's XML output and external system requirements in transformation scenarios.
What is the workflow to chain a Document Transformation system to a Connector integration for the purpose of transforming the output?
To chain a Document Transformation system to a Connector Integration, you must configure the Connector Integration System's Business Process (BP) to include a 'Service step of Fire Integration', which triggers the Document Transformation after the connector completes.
From Workday documentation:
''To execute a Document Transformation after a connector integration, use the Fire Integration service step in the connector's business process to trigger the Document Transformation integration.''
This allows Workday to chain multiple integrations, such as taking the output of a Core Connector and sending it through a transformation step (e.g., XSLT) before delivering to an endpoint.
Why other options are incorrect:
A . Fire Integration in the DT BP is not used to call itself.
B . 'Integration step' in BP is not a valid step type.
C . Same issue --- DT's own BP doesn't call itself or other integrations.
You are developing a Core Connector: Worker integration with DIS enabled. You configure the Population Eligibility to include all US workers and also define the Eligibility Criterion field to return only those workers assigned to the Sales organization.
When you run the integration, the output includes all US workers instead of just those in Sales.
What should you do to ensure only workers in the Sales organization appear in the output?
Population Eligibility controls which workers are included in the Core Connector output population. In this scenario, the Population Eligibility is configured to include all US workers, so the connector correctly outputs that entire eligible population. The Eligibility Criterion field does not replace Population Eligibility as the population filter. It can support eligibility-related logic, but it is not the correct place to enforce the final worker population restriction when the actual extract should include only Sales workers. To fix the output, the Sales organization condition must be moved into the Population Eligibility rule itself. Updating the criterion field or running a full file would not solve the problem because the population filter would still include all US workers. The integration population must be filtered at the source.
================
Refer to the following XML to answer the question below.
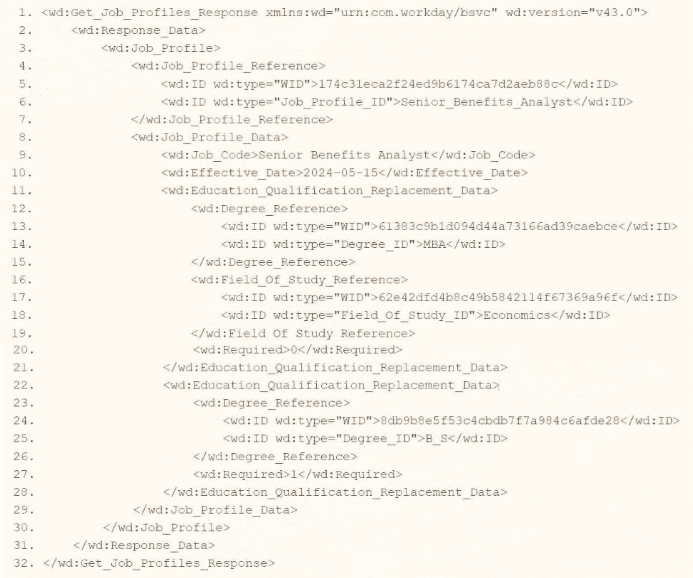
You are an integration developer and need to write XSLT to transform the output of an EIB which is making a request to the Get Job Profiles web service operation. The root template of your XSLT matches on the
As an integration developer working with Workday, you are tasked with transforming the output of an Enterprise Interface Builder (EIB) that calls the Get_Job_Profiles web service operation. The provided XML shows the response from this operation, and you need to write XSLT to select the value of the <wd:ID> element where the wd:type attribute equals 'Job_Profile_ID.' The root template of your XSLT matches on <wd:Get_Job_Profiles_Response> and applies templates to <wd:Job_Profile>. Within this template, you use the <xsl:value-of> element to extract the value. Let's analyze the XML structure, the requirement, and each option to determine the correct XPath syntax.
Understanding the XML and Requirement
The XML snippet provided is a SOAP response from the Get_Job_Profiles web service operation in Workday, using the namespace xmlns:wd='urn:com.workday/bsvc' and version wd:version='v43.0'. Key elements relevant to the question include:
The root element is <wd:Get_Job_Profiles_Response>.
It contains <wd:Response_Data>, which includes <wd:Job_Profile> elements.
Within <wd:Job_Profile>, there is <wd:Job_Profile_Reference>, which contains multiple <wd:ID> elements, each with a wd:type attribute:
<wd:ID wd:type='WID'>1740d3eca2f2ed9b6174ca7d2ae88c8c</wd:ID>
<wd:ID wd:type='Job_Profile_ID'>Senior_Benefits_Analyst</wd:ID>
The task is to select the value of the <wd:ID> element where wd:type='Job_Profile_ID' (e.g., 'Senior_Benefits_Analyst') using XPath within an XSLT template that matches <wd:Job_Profile>. The <xsl:value-of> element outputs the value of the selected node, so you need the correct XPath path from the <wd:Job_Profile> context to the specific <wd:ID> element with the wd:type attribute value 'Job_Profile_ID.'
Analysis of Options
Let's evaluate each option based on the XML structure and XPath syntax rules:
Option A: wd:Job_Profile_Reference/wd:ID/wd:type='Job_Profile_ID'
This XPath attempts to navigate from wd:Job_Profile_Reference to wd:ID, then to wd:type='Job_Profile_ID'. However, there are several issues:
wd:type='Job_Profile_ID' is not valid XPath syntax. In XPath, to filter based on an attribute value, you use the attribute selector [@attribute='value'], not a direct comparison like wd:type='Job_Profile_ID'.
wd:type is an attribute of <wd:ID>, not a child element or node. This syntax would not select the <wd:ID> element itself but would be interpreted as trying to match a nonexistent child node or property, resulting in an error or no match.
This option is incorrect because it misuses XPath syntax for attribute filtering.
Option B: wd:Job_Profile_Reference/wd:ID/@wd:type='Job_Profile_ID'
This XPath navigates to wd:Job_Profile_Reference/wd:ID and then selects the @wd:type attribute, comparing it to 'Job_Profile_ID' with =@wd:type='Job_Profile_ID'. However:
The =@wd:type='Job_Profile_ID' syntax is invalid in XPath. To filter based on an attribute value, you use [@wd:type='Job_Profile_ID'] as a predicate, not an equality comparison in this form.
This XPath would select the wd:type attribute itself (e.g., the string 'Job_Profile_ID'), not the value of the <wd:ID> element. Since <xsl:value-of> expects a node or element value, selecting an attribute directly would not yield the desired 'Senior_Benefits_Analyst' value.
This option is incorrect due to the invalid syntax and inappropriate selection of the attribute instead of the element value.
Option C: wd:Job_Profile_Reference/wd:ID[@wd:type='Job_Profile_ID']
This XPath navigates from wd:Job_Profile_Reference to wd:ID and uses the predicate [@wd:type='Job_Profile_ID'] to filter for <wd:ID> elements where the wd:type attribute equals 'Job_Profile_ID.'
In the XML, <wd:Job_Profile_Reference> contains:
<wd:ID wd:type='WID'>1740d3eca2f2ed9b6174ca7d2ae88c8c</wd:ID>
<wd:ID wd:type='Job_Profile_ID'>Senior_Benefits_Analyst</wd:ID>
The predicate [@wd:type='Job_Profile_ID'] selects the second <wd:ID> element, whose value is 'Senior_Benefits_Analyst.'
Since the template matches <wd:Job_Profile>, and <wd:Job_Profile_Reference> is a direct child of <wd:Job_Profile>, this path is correct:
<wd:Job_Profile> <wd:Job_Profile_Reference> <wd:ID[@wd:type='Job_Profile_ID']>.
When used with <xsl:value-of select='wd:Job_Profile_Reference/wd:ID[@wd:type='Job_Profile_ID']'/>, it outputs 'Senior_Benefits_Analyst,' fulfilling the requirement.
This option is correct because it uses proper XPath syntax for attribute-based filtering and selects the desired <wd:ID> value.
Option D: wd:Job_Profile_Reference/wd:ID/[@wd:type='Job_Profile_ID']
This XPath is similar to Option C but includes an extra forward slash before the predicate: wd:ID/[@wd:type='Job_Profile_ID']. In XPath, predicates like [@attribute='value'] are used directly after the node name (e.g., wd:ID[@wd:type='Job_Profile_ID']), not separated by a slash. The extra slash is syntactically incorrect and would result in an error or no match, as it implies navigating to a child node that doesn't exist.
This option is incorrect due to the invalid syntax.
Why Option C is Correct
Option C, wd:Job_Profile_Reference/wd:ID[@wd:type='Job_Profile_ID'], is the correct XPath syntax because:
It starts from the context node <wd:Job_Profile> (as the template matches this element) and navigates to <wd:Job_Profile_Reference/wd:ID>, using the predicate [@wd:type='Job_Profile_ID'] to filter for the <wd:ID> element with wd:type='Job_Profile_ID'.
It correctly selects the value 'Senior_Benefits_Analyst,' which is the content of the <wd:ID> element where wd:type='Job_Profile_ID'.
It uses standard XPath syntax for attribute-based filtering, aligning with Workday's XSLT implementation for web service responses.
When used with <xsl:value-of>, it outputs the required value, fulfilling the question's requirement.
Practical Example in XSLT
Here's how this might look in your XSLT:
<xsl:template match='wd:Job_Profile'>
<xsl:value-of select='wd:Job_Profile_Reference/wd:ID[@wd:type='Job_Profile_ID']'/>
</xsl:template>
This would output 'Senior_Benefits_Analyst' for the <wd:ID> element with wd:type='Job_Profile_ID' in the XML.
Verification with Workday Documentation
The Workday Pro Integrations Study Guide and SOAP API Reference (available via Workday Community) detail the structure of the Get_Job_Profiles response and how to use XPath in XSLT for transformations. The XML structure shows <wd:Job_Profile_Reference> containing <wd:ID> elements with wd:type attributes, and the guide emphasizes using predicates like [@wd:type='value'] to filter based on attributes. This is a standard practice for navigating Workday web service responses.
Workday Pro Integrations Study Guide Reference
Section: XSLT Transformations in EIBs -- Describes using XSLT to transform web service responses, including selecting elements with XPath and attribute predicates.
Section: Workday Web Services -- Details the Get_Job_Profiles operation and its XML output structure, including <wd:Job_Profile_Reference> and <wd:ID> with wd:type attributes.
Section: XPath Syntax -- Explains how to use predicates like [@wd:type='Job_Profile_ID'] for attribute-based filtering in Workday XSLT.
Workday Community SOAP API Reference -- Provides examples of XPath navigation for Workday web service responses, including attribute selection.
Option C is the verified answer, as it correctly selects the <wd:ID> value with wd:type='Job_Profile_ID' using the appropriate XPath syntax within the <wd:Job_Profile> template context.
You are configuring a Core Connector integration that will send data to an external vendor. The vendor requires that the integration output file includes a unique Batch ID in its filename.
This ID must follow the format VNDR_YEARMONTH_seq.xml, where YEAR is the four-digit year, MONTH is the two-digit month, and seq is a five-digit sequence number that must reset to 00001 at the beginning of each new month.
Which settings must you configure on the integration Filename Sequence Generator to produce this Batch ID filename?
The required filename needs a static prefix, runtime date tokens, and a monthly resetting sequence. The correct Workday-style pattern uses bracketed date tokens: [yyyy] for the four-digit year and [MM] for the two-digit month. The sequence token [seq] supplies the next sequence number. Because the sequence must be five digits, Padding must be set to 5 so values appear as 00001, 00002, and so on. Restart Frequency must be Month because the sequence resets at the beginning of each new month. Option B incorrectly treats the tokens as literal text and resets yearly. Option C uses invalid token names and resets daily. Option D uses nonstandard token names and lacks the required five-digit padding.
================
- Select Question Types you want
- Set your Desired Pass Percentage
- Allocate Time (Hours : Minutes)
- Create Multiple Practice tests with Limited Questions
- Customer Support
Deborah Anderson
1 month agoSandra Turner
2 months agoJohn Green
2 months agoElizabeth Hernandez
3 months agoPaul Harris
3 months agoRachel Davis
4 months agoFrank Murphy
4 months agoJustin Scott
5 months agoTiffany Collins
5 months agoSarah Torres
6 months agoAshley Mitchell
6 months agoEmma Lewis
6 months agoMonica Carter
6 months agoJessica Lee
6 months agoGary Collins
6 months agoAngela Nguyen
6 months agoHerman
7 months agoKarrie
7 months agoJaclyn
8 months agoColton
8 months agoJoaquin
8 months agoKathrine
8 months agoGilma
9 months agoAlpha
9 months agoEve
9 months agoLigia
9 months agoAmie
10 months agoLaquita
10 months agoDominga
10 months agoRosalind
10 months agoJody
10 months agoKristine
11 months agoLeonida
11 months agoShonda
11 months agoReita
11 months agoJohnson
12 months agoLawana
12 months agoLevi
1 year ago