
Free Preparation Discussions
 MENU

Microsoft AI-901 Exam Questions
Free Microsoft AI-901 Exam Actual Questions
Note: Premium Questions for AI-901 were last updated On Oct. 23, 2026 (see below)
Capturing text from images is an example of which type of Al capability?
You use natural language processing to process text from a Microsoft news story. You receive the output shown in the following table.
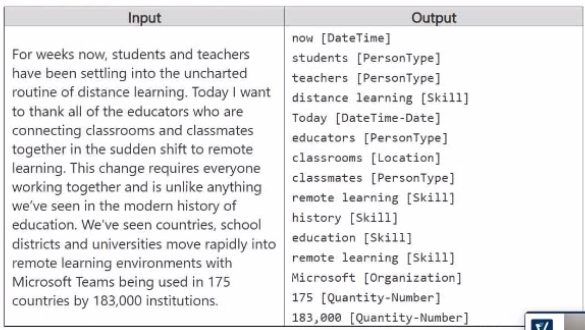
Which type of natural language processing was performed?
The output identifies text values and labels them with entity categories, such as:
now [DateTime] students [PersonType] Microsoft [Organization] 175 [Quantity-Number] Today [DateTime-Date]
This is entity recognition, also known as Named Entity Recognition (NER). NER identifies and categorizes entities in unstructured text, such as people, organizations, locations, dates, quantities, numbers, and other named or structured values.
Why the other options are incorrect:
Your company wants to build a recycling machine for bottles. The recycling machine must use cameras to automatically identify bottles of the correct shape and reject all other items.
Which type of Al workload should the company use?
A recycling machine that uses cameras to identify bottles of the correct shape and reject other items requires analysis of visual input. This is a computer vision workload.
Computer vision is used for image and video analysis tasks such as object detection, classification, shape recognition, and visual inspection.
The other options are incorrect:
You are developing an application that continuously transcribes speech from a default microphone by using Azure Speech in Microsoft Foundry Tools.
You need to perform speech-to-text transcription from the microphone.
Which Python class should you use?
You are developing an application that processes voicemail recordings by using Azure Content Understanding in Foundry Tools.
Which feature does Azure Content Understanding use to convert audio to text?
Azure Content Understanding uses transcription to convert audio content, such as voicemail recordings, into text. Microsoft's Azure Content Understanding audio documentation states that transcription converts conversational audio into searchable and analyzable text-based transcripts.
Option A. Voice Live is not the feature used by Content Understanding to convert voicemail recordings into text. Option B. key phrase extraction identifies important phrases after text is available; it is not the audio-to-text conversion step. Option D. optical character recognition (OCR) is for extracting text from images or documents, not audio.
Therefore, the correct answer is C. transcription.
- Select Question Types you want
- Set your Desired Pass Percentage
- Allocate Time (Hours : Minutes)
- Create Multiple Practice tests with Limited Questions
- Customer Support
Elizabeth Hernandez
1 month agoPatricia Flores
2 months agoHarold Gonzalez
2 months agoRebecca Green
21 days agoGeorge Nelson
2 months agoPaul Garcia
3 months agoAmanda Turner
3 months agoFrank Johnson
3 months agoAngela Gonzalez
4 months agoMonica Evans
4 months agoLisa Mitchell
4 months agoMelissa Martinez
5 months agoNancy Jones
5 months agoWilliam Torres
6 months agoEdward Brown
6 months agoKaren Collins
6 months ago