
Free Preparation Discussions
 MENU

Juniper JN0-650 Exam Questions
- Topic 1: Interior Gateway Protocols (IGPs): This domain covers internal routing protocols operating within a single autonomous system, including OSPFv2, OSPFv3, and routing policy implementation, along with configuration, troubleshooting, and monitoring skills.
- Topic 2: BGP: This section focuses on Border Gateway Protocol operations including route selection, next hop resolution, BGP attributes, communities, load balancing, IPv4/IPv6 address families, advanced options, and routing policy implementation.
- Topic 3: IP Multicast: This domain addresses one-to-many communication using multicast routing, covering addressing, ASM vs SSM models, RPF, IGMP/snooping, PIM sparse-mode, rendezvous points, Anycast RP, MSDP, and routing policies.
- Topic 4: Ethernet Switching and Spanning Tree: This section covers advanced Layer 2 switching including filter-based VLANs, private VLANs, MVRP, Layer 2 tunneling via Q-in-Q and L2PT, plus MSTP and VSTP protocols.
- Topic 5: Layer 2 Authentication and Access Control: This domain examines network access control mechanisms including 802.1x, MAC RADIUS, captive portal, server fail fallback, guest VLANs, and multi-method authentication considerations.
- Topic 6: IP Telephony Features: This section focuses on features supporting VoIP deployments including Power over Ethernet, LLDP/LLDP-MED protocols, and voice VLAN implementation.
- Topic 7: Class of Service (CoS): This domain covers QoS mechanisms in Junos including CoS processing, header fields, forwarding classes, classification, policers, schedulers, drop profiles, shaping, and rewrite rules.
- Topic 8: EVPN: This section addresses Ethernet VPN technology for Layer 2 over Layer 3 connectivity, covering EVPN route types, VXLAN encapsulation, and multi-homing configurations.
Free Juniper JN0-650 Exam Actual Questions
Note: Premium Questions for JN0-650 were last updated On Oct. 30, 2026 (see below)
Exhibit.
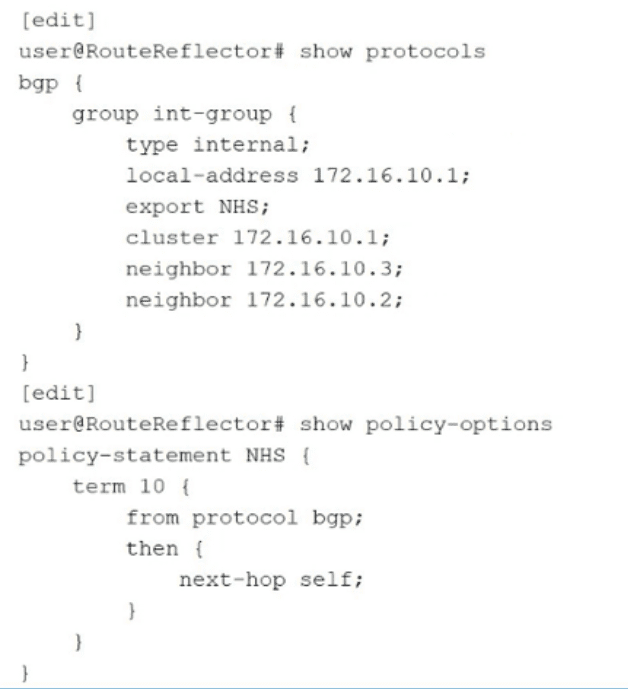
You have determined that traffic in your network is being routed through your route reflector instead of using the optimal path. Referring to the exhibit, what are two configuration changes on the route reflector that would solve the problem? (Choose two.)
The exhibit shows a BGP Route Reflector (RR) configuration where an export policy named NHS (Next-Hop Self) is applied to the internal BGP group int-group. The policy NHS sets the next-hop self attribute for BGP routes.
The Problem (Traffic Tromboning): In a standard BGP Route Reflector design, the RR should reflect routes without modifying the BGP next-hop attribute. By applying a next-hop self policy on the export to clients, the RR tells all its clients that it is the exit point for those routes. Consequently, all data plane traffic is sent to the RR first before being forwarded to the actual destination, rather than following the optimal direct path between clients. This is known as 'traffic tromboning' or suboptimal routing.
The Solution (Option C): The most direct way to fix this is to delete the export policy that is forcing the next-hop to be the RR. By deleting protocols bgp group int-group export NHS, the RR will resume standard behavior and reflect the original next-hop received from the route source, allowing clients to route traffic directly to the correct destination.
The Refined Solution (Option D): If you must keep the NHS policy (perhaps for routes learned from external peers), you should ensure it only applies to those specific routes. By adding from route-type internal to the policy term and then potentially changing the logic (or simply narrowing the scope), you can prevent the RR from incorrectly applying next-hop self to internal routes that it is merely reflecting. In the context of this specific problem, Option D combined with a change in the policy's action or scope helps ensure reflected internal routes maintain their original, optimal next-hops.
Option A is incorrect because setting next-hop self for external routes is common practice, but it doesn't solve the problem of internal reflected routes being diverted to the RR.
Option B is incorrect because applying this as an import policy would change how the RR itself sees the routes, but it wouldn't fix the attributes being sent out to the clients in the reflection process.
Exhibit
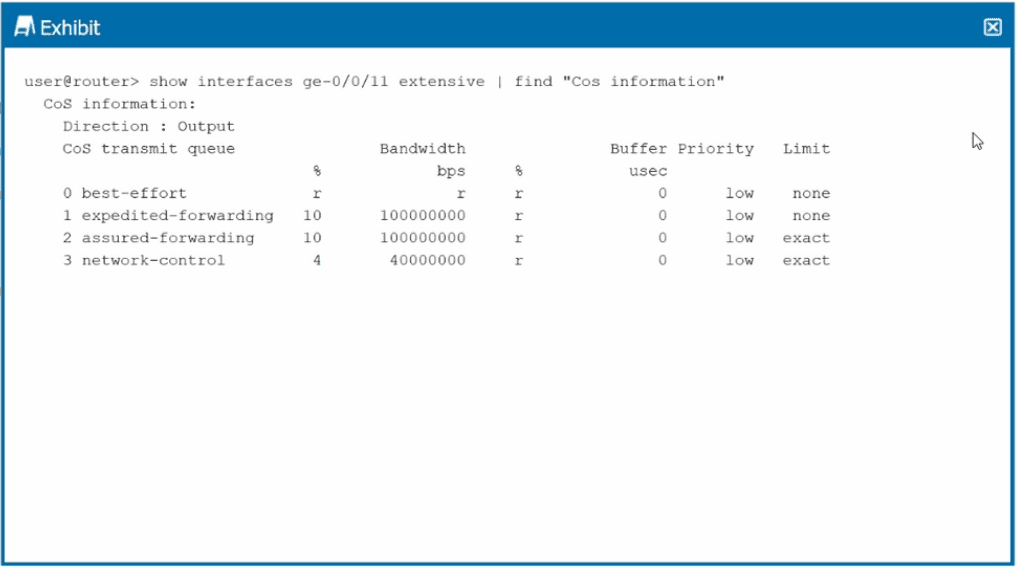
Referring to the exhibit, which two statements are correct? (Choose two.)
The exhibit shows the Class of Service (CoS) transmit queue information for interface ge-0/0/11. To determine the correct behavior, we must analyze the bandwidth allocations and the queue limit settings:
Bandwidth Calculation (Option A): In Junos OS, when multiple queues are assigned specific percentages of bandwidth, the 'remainder' (represented by 'r') is the total interface bandwidth minus the sum of the explicitly configured percentages.
Bandwidth assigned to Queue 1 (EF) = 10%.
Bandwidth assigned to Queue 2 (AF) = 10%.
Bandwidth assigned to Queue 3 (NC) = 4%.
Total explicitly assigned = $10\% + 10\% + 4\% = 24\%$.
Remainder for Queue 0 (Best Effort) = $100\% - 24\% = 76\%$.
'Limit: exact' Behavior (Option B): The exhibit shows that Queue 2 (assured-forwarding) has a Limit set to exact.
By default, a queue in Junos can consume more than its allocated bandwidth if other queues are idle.
However, when the exact keyword is applied to the transmit-rate (transmission rate), the queue is strictly rate-limited to its configured percentage.
This means that traffic in Queue 2 will be capped at 10% of the interface bandwidth regardless of whether the network is congested or not. If the traffic exceeds 10%, the excess will be dropped or buffered to match the exact rate.
Option C is incorrect because 100% of the bandwidth is not reserved for a single queue; it is distributed across four queues.
Option D is less accurate than B because it implies the drop behavior only occurs during congestion. The exact parameter enforces the limit even when the rest of the interface is completely idle.
When configuring Q-in-Q tunneling, which type of tunneling involves the swapping of S-VLANs with C-VLANs?
In a Juniper Q-in-Q (Layer 2 tunneling) environment, VLAN rewrites (specifically the swap operation) provide the most granular control over how customer traffic (C-VLANs) is mapped to service provider traffic (S-VLANs).
VLAN Rewrites (The Swap Operation): This method involves replacing the incoming customer VLAN tag with a service provider tag as the frame enters the tunnel. This is technically a 'swap' because the original C-VLAN tag is removed and the S-VLAN tag is written in its place. At the egress of the tunnel, the S-VLAN tag is swapped back for the original C-VLAN tag. This is often used when different customers use the same C-VLAN IDs and the provider needs to keep them unique within their core.
Many-to-Many: This is a mapping style where multiple customer VLANs are mapped to multiple service provider VLANs, but it typically relies on the 'push' (stacking) operation rather than a literal 'swap' of the tag itself.
All-in-One: This is the simplest form of Q-in-Q where all traffic entering an interface is 'pushed' into a single S-VLAN tag, regardless of any existing C-VLAN tags. No swapping occurs; the original tags are simply buried under the new provider tag.
L2PT (Layer 2 Protocol Tunneling): This is a feature used to tunnel Layer 2 control protocols (like STP, CDP, or LLDP) across a provider network by encapsulating them or changing their destination MAC addresses. It does not involve the swapping of VLAN tags.
The network you support currently has a mixture of MC-LAG and Virtual Chassis being used to provide redundant connectivity from various IDFs. A project to modernize the architecture and move to EVPN-VXLAN using ESI-LAG will be starting soon. You want to avoid IDFs losing connectivity as the core devices are migrated to EVPN-VXLAN. Which action will accomplish this task?
In an EVPN-VXLAN environment using ESI-LAG (Ethernet Segment Identifier Link Aggregation), the Core Isolation feature is a safety mechanism designed to prevent traffic blackholing. When a leaf switch (acting as a VTEP) loses its BGP peering or its link to the IP fabric core, it assumes it is 'isolated' from the rest of the network. To protect the network, the switch automatically shuts down its local member links of any multi-homed ESI-LAG to force traffic to the peer switch that still has core connectivity.
However, during a migration or in specific transitional topologies where the core might be temporarily unreachable or not yet fully established, this feature can cause the leaf switches to shut down all downstream IDF (Intermediate Distribution Frame) connections, leading to a total loss of connectivity.
The Solution (Option C): By enabling the no-core-isolation statement under the [edit protocols evpn] hierarchy, you instruct the switch to disable this automatic shutdown behavior. This ensures that even if the BGP session or core links are not yet stable during the migration process, the ESI-LAG interfaces remain Up, allowing the IDFs to maintain connectivity to their local default gateways or other local resources.
Why others are incorrect: Enabling EVPN-VXLAN before migration (Option A) does not address the isolation logic. Removing MC-LAG/Virtual Chassis links prematurely (Option B) would cause an immediate outage. The network-isolation-profile (Option D) is typically used for different loop prevention scenarios and does not override the specific core-isolation check that affects multi-homed ESIs.
What causes IBGP route flapping in enterprise networks?
In enterprise networks utilizing Junos OS, IBGP (Internal BGP) route flapping is frequently caused by recursive routing failures within the underlying IGP (Interior Gateway Protocol), such as OSPF or IS-IS.
Recursive Next-Hop Resolution: Unlike EBGP, where the neighbor is typically directly connected, IBGP neighbors are often several hops away. Consequently, an IBGP route's protocol next-hop is usually a loopback IP address that requires a recursive lookup to resolve. The router must consult its unicast routing table (typically inet.0 or inet.3) to find a physical path to that next-hop.
The Flapping Mechanism: A 'flap' occurs when a route is repeatedly withdrawn and readvertised. If the IGP path used to resolve the BGP next-hop becomes unstable or if the BGP route itself is inadvertently used to resolve its own next-hop (a recursive loop), the BGP next-hop becomes unreachable.
Impact on Routing Table: When the next-hop cannot be resolved, the BGP route is considered invalid and is withdrawn from the routing table. Once the route is withdrawn, the original IGP path to the next-hop often becomes valid again, causing the BGP route to be readvertised. This cycle of withdrawal and readvertisement creates the instability known as flapping.
Why other options are incorrect: Packet misordering (Option A) and community tagging (Option B) may affect performance or policy but do not cause a route to be withdrawn and readvertised in this cyclical manner. While update intervals (Option C) control how quickly changes are sent, they are not the root cause of the reachability failure that triggers the flap itself.
- Select Question Types you want
- Set your Desired Pass Percentage
- Allocate Time (Hours : Minutes)
- Create Multiple Practice tests with Limited Questions
- Customer Support
Carol Cook
1 month agoRebecca Martinez
2 months agoAnthony Flores
3 months agoMichael Brown
4 months agoSusan Morgan
5 months agoJames Flores
5 months agoIGPs Perez
6 months agoEVPN Smith
5 months agoBGP Williams
6 months agoIP Multicast Martinez
5 months agoGeorge Campbell
6 months agoDavid Ramirez
6 months agoDorothy Adams
6 months agoMatthew Bell
6 months agoJames Martinez
6 months agoRobert Bailey
6 months agoDion
7 months agoRusty
7 months agoSunny
8 months agoTenesha
8 months agoJosefa
8 months agoNorah
8 months agoAlbina
9 months agoKirby
9 months agoWillis
9 months agoLeonard
9 months agoMaricela
10 months agoNathalie
10 months ago