
Free Preparation Discussions
 MENU

Google Associate Data Practitioner Exam Questions
- Google Cloud Certified Certifications
- Google Data Practitioner Certifications
Free Google Associate Data Practitioner Exam Actual Questions
Note: Premium Questions for Associate Data Practitioner were last updated On Oct. 25, 2026 (see below)
You are working with a large dataset of customer reviews stored in Cloud Storage. The dataset contains several inconsistencies, such as missing values, incorrect data types, and duplicate entries. You need to clean the data to ensure that it is accurate and consistent before using it for analysis. What should you do?
Using BigQuery to batch load the data and perform cleaning and analysis with SQL is the best approach for this scenario. BigQuery provides powerful SQL capabilities to handle missing values, enforce correct data types, and remove duplicates efficiently. This method simplifies the pipeline by leveraging BigQuery's built-in processing power for both cleaning and analysis, reducing the need for additional tools or services and minimizing complexity.
Your retail company wants to analyze customer reviews to understand sentiment and identify areas for improvement. Your company has a large dataset of customer feedback text stored in BigQuery that includes diverse language patterns, emojis, and slang. You want to build a solution to classify customer sentiment from the feedback text. What should you do?
Comprehensive and Detailed in Depth
Why B is correct:AutoML Natural Language is designed for text classification tasks, including sentiment analysis, and can handle diverse language patterns without extensive preprocessing.
AutoML can train a custom model with minimal coding.
Why other options are incorrect:A: Unnecessary extra preprocessing. AutoML can handle the raw data.
C: Dataproc and Spark are overkill for this task. AutoML is more efficient and easier to use.
D: Developing a custom TensorFlow model requires significant expertise and time, which is not efficient for this scenario.
AutoML Natural Language: https://cloud.google.com/natural-language/automl/docs
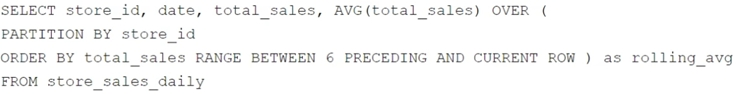
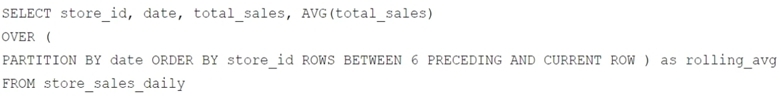
Your company has several retail locations. Your company tracks the total number of sales made at each location each day. You want to use SQL to calculate the weekly moving average of sales by location to identify trends for each store. Which query should you use?
A)
B)
C)
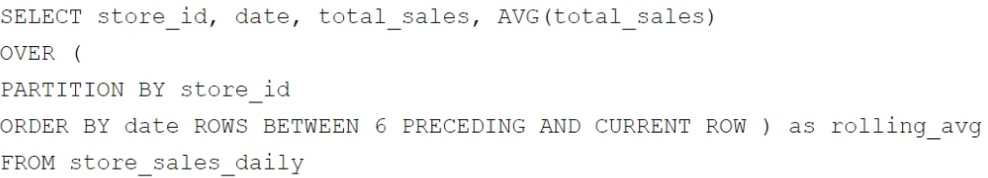
D)
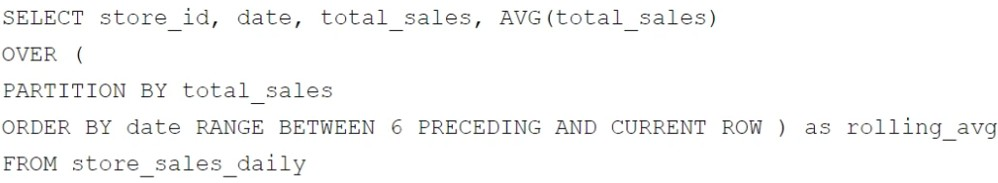
To calculate the weekly moving average of sales by location:
The query must group by store_id (partitioning the calculation by each store).
The ORDER BY date ensures the sales are evaluated chronologically.
The ROWS BETWEEN 6 PRECEDING AND CURRENT ROW specifies a rolling window of 7 rows (1 week if each row represents daily data).
The AVG(total_sales) computes the average sales over the defined rolling window.
Chosen query meets these requirements:
Extract from Google Documentation: From 'Analytic Functions in BigQuery' (https://cloud.google.com/bigquery/docs/reference/standard-sql/analytic-function-concepts): 'Use ROWS BETWEEN n PRECEDING AND CURRENT ROW with ORDER BY a time column to compute moving averages over a fixed number of rows, such as a 7-day window, partitioned by a grouping key like store_id.' Reference: Google Cloud Documentation - 'BigQuery Window Functions' (https://cloud.google.com/bigquery/docs/reference/standard-sql/window-function-calls).
You are working on a project that requires analyzing daily social media dat
a. You have 100 GB of JSON formatted data stored in Cloud Storage that keeps growing.
You need to transform and load this data into BigQuery for analysis. You want to follow the Google-recommended approach. What should you do?
Comprehensive and Detailed in Depth
Why C is correct:Dataflow is a fully managed service for transforming and enriching data in both batch and streaming modes.
Dataflow is googles recomended way to transform large datasets.
It is designed for parallel processing, making it suitable for large datasets.
Why other options are incorrect:A: Manual downloading and scripting is not scalable or efficient.
B: Cloud Run functions are for stateless applications, not large data transformations.
D: While Cloud Data fusion could work, Dataflow is more optimized for large scale data transformation.
Dataflow: https://cloud.google.com/dataflow/docs
Query successful
You need to create a data pipeline for a new application. Your application will stream data that needs to be enriched and cleaned. Eventually, the data will be used to train machine learning models. You need to determine the appropriate data manipulation methodology and which Google Cloud services to use in this pipeline. What should you choose?
Comprehensive and Detailed In-Depth
Streaming data requiring enrichment and cleaning before ML training suggests an ETL (Extract, Transform, Load) approach, with a focus on real-time processing and a data warehouse for ML.
Option A: ETL with Dataflow (streaming transformations) and BigQuery (storage/ML training) is Google's recommended pattern for streaming pipelines. Dataflow handles enrichment/cleaning, and BigQuery supports ML model training (BigQuery ML).
Option B: ETL with Cloud Data Fusion to Cloud Storage is batch-oriented and lacks streaming focus. Cloud Storage isn't ideal for ML training directly.
Option C: ELT (load then transform) with Cloud Storage to Bigtable is misaligned---Bigtable is for NoSQL, not ML training or post-load transformation.
Option D: ELT with Cloud SQL to Analytics Hub is for relational data and data sharing, not streaming or ML. Reference: Google Cloud Documentation - 'Dataflow: ETL Patterns' (https://cloud.google.com/dataflow/docs/guides), 'BigQuery ML' (https://cloud.google.com/bigquery-ml).
Option D: ELT with Cloud SQL to Analytics Hub is for relational data and data sharing, not streaming or ML. Reference: Google Cloud Documentation - 'Dataflow: ETL Patterns' (https://cloud.google.com/dataflow/docs/guides), 'BigQuery ML' (https://cloud.google.com/bigquery-ml).
- Select Question Types you want
- Set your Desired Pass Percentage
- Allocate Time (Hours : Minutes)
- Create Multiple Practice tests with Limited Questions
- Customer Support
Bao Bui
15 days agoHao Tanaka
25 days agoZainab Hashmi
2 months agoSumayya Rizvi
2 months agoOlivia Campbell
3 months ago